Create AI-Ready Enterprise Content with the Syncfusion .NET Document Chunking Library [Webinar Show Notes]
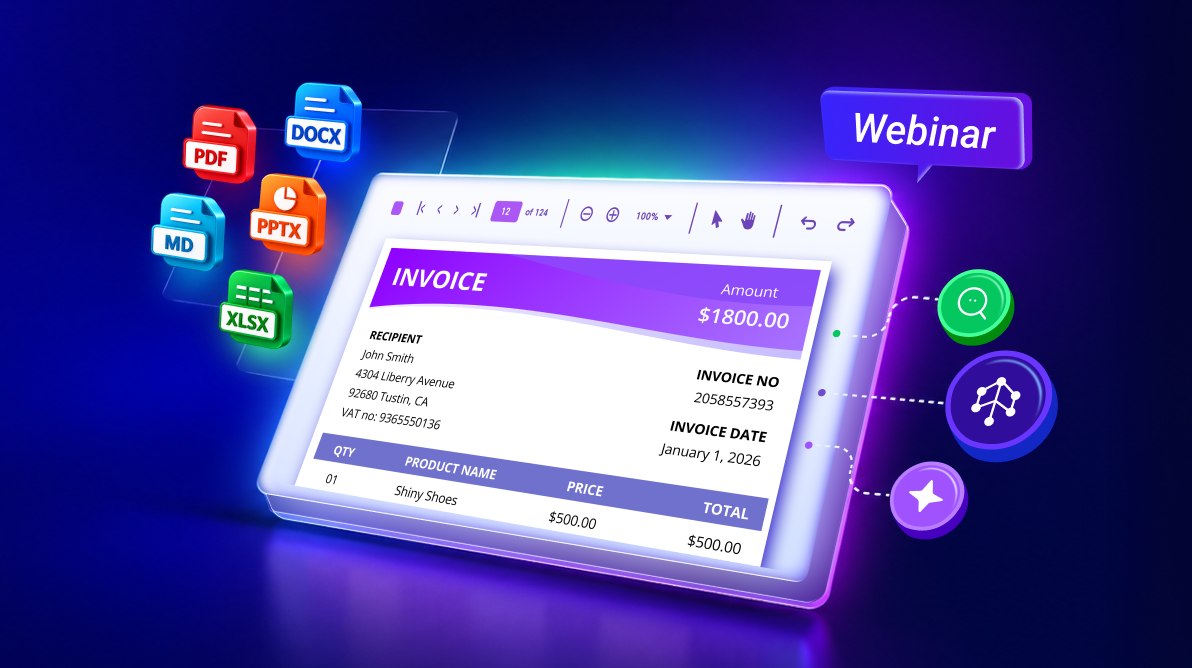
In this webinar, presenter Anantha Lakshmi Kannan demonstrated how the Syncfusion® .NET Document Chunking Library prepares enterprise documents for retrieval and AI workflows.
The session used ASP.NET Core applications to demonstrate format-specific chunking modes, configurable chunk size and token overlap, structured JSON output, metadata, citation information, and RAG-based document question answering.
If you missed the webinar, the recording is available on our YouTube channel and is embedded below.
Timestamps
[00:00] Introduction & Webinar Overview
[01:00] AI Challenges with Enterprise Documents
[03:00] Understanding Document Chunking
[04:17] Prerequisites & Project Setup
[05:00] Building a Document Chunking Service
[09:05] Demo: Chunking a Word Document
[12:06] Demo: Chunking an Excel Workbook
[14:57] Using Chunks in a RAG Workflow
[16:20] Document Indexing & Embedding Generation
[18:25] Retrieving Relevant Chunks for Q&A
[21:10] Demo: AI-Powered Document Question Answering
[24:20] Real-World Use Cases
[25:06] Key Takeaways & Closing Remarks
Document Chunking and JSON Output
The first application demonstrates how the Syncfusion .NET Document Chunking Library transforms supported enterprise documents into structured chunks. Developers can configure format-specific chunking modes, chunk size, and token overlap, then inspect the generated content, metadata, and citation information as JSON.
Explore the ASP.NET Core Document Chunking JSON demo.
AI-Integrated Document Q&A
The second application demonstrates how prepared document chunks can support a RAG-based question-answering workflow. The application generates embeddings for the chunks, stores them for retrieval, identifies the top-matching content for a user’s question, and supplies that context to an AI model to generate a grounded response.
The Syncfusion .NET Document Chunking Library handles document preparation, while the same application implements embedding generation, storage, retrieval, and AI-model integration separately.
Conclusion
The Syncfusion .NET Document Chunking Library helps developers transform PDF, Word, Excel, PowerPoint, and Markdown content into structured, traceable chunks for search, document Q&A, and RAG workflows.
Frequently Asked Questions
Is there built-in functionality to chunk documents straight from DOCX Editor for Angular? Or do they have to be saved as DOCX and processed later?
There is currently no built-in integration between the Angular DOCX Editor and the .NET Document Chunking Library. However, the Angular DOCX Editor can export the currently edited document as a DOCX Blob. The application can send the Blob to an ASP.NET Core backend, convert it to a stream, and pass it to the .NET Document Chunking Library for processing. The document does not need to be permanently saved before chunking.
There must be some extensibility story going forward. The document types chosen are the correct ones, but there are many more file formats (even video formats, XML-based formats) that people will want to add.
Currently, the Syncfusion .NET Document Chunking Library supports Excel, Word, PDF, PowerPoint, and Markdown documents. Other formats, including video and general XML files, are not currently supported and would require separate extraction or conversion before chunking. Support for additional formats is planned for future releases
Can someone introduce a new “document type” for, say, a C# file?
Currently, the library does not provide code-aware chunking, such as splitting a codebase by file, class, function, or method based on its syntax. If code is included in a supported Markdown or Word document, the library processes it as regular document content rather than applying code-specific chunking.
There are classes that allow you to chunk different file types, for which an embedding can be generated, given token number constraints and overlap. I wonder if you have thought about code-embedding, so code bases can be embedded.
The current library does not split source code by syntax elements such as files, classes, methods, or functions.
Be the first to get updates
PakarPBN
A Private Blog Network (PBN) is a collection of websites that are controlled by a single individual or organization and used primarily to build backlinks to a “money site” in order to influence its ranking in search engines such as Google. The core idea behind a PBN is based on the importance of backlinks in Google’s ranking algorithm. Since Google views backlinks as signals of authority and trust, some website owners attempt to artificially create these signals through a controlled network of sites.
In a typical PBN setup, the owner acquires expired or aged domains that already have existing authority, backlinks, and history. These domains are rebuilt with new content and hosted separately, often using different IP addresses, hosting providers, themes, and ownership details to make them appear unrelated. Within the content published on these sites, links are strategically placed that point to the main website the owner wants to rank higher. By doing this, the owner attempts to pass link equity (also known as “link juice”) from the PBN sites to the target website.
The purpose of a PBN is to give the impression that the target website is naturally earning links from multiple independent sources. If done effectively, this can temporarily improve keyword rankings, increase organic visibility, and drive more traffic from search results.
Streaming Film
Nonton Film gratis
Jasa Backlink
Download Anime Batch